Five architectures. One workflow.
Unified, MoT, MoT-Joint, MoT-IDM and Hidden share data, training, checkpoint and evaluation interfaces.
A unified research codebase
EasyWAM connects modular World Action Models, data processing, distributed training, parameter-efficient fine-tuning and scalable evaluation in one reproducible workflow.
01 / overview
From sparse video decoding to resumable evaluation, EasyWAM makes the entire WAM loop inspectable and repeatable.

Unified, MoT, MoT-Joint, MoT-IDM and Hidden share data, training, checkpoint and evaluation interfaces.
Wan2.2-TI2V-5B, Cosmos-Predict2.5-2B and FLUX.2 Klein-4B, with full-parameter training and LoRA fine-tuning.
FlashAttention 2/3/4, sparse video decoding, text and prompt caches, DeepSpeed ZeRO, dynamic inference batches and resumable evaluation.
LIBERO, LIBERO-Plus, RoboTwin, RoboDojo and RoboCasa365, with distributed evaluation and result summaries.
02 / quick start
Choose a task and copy commands from the project README. Follow the linked guides to prepare datasets, model weights and simulators.
Run from the repository root after cloning. FlashAttention is optional and depends on your GPU.
conda create -n easywam python=3.10 -y
conda activate easywam
pip install -U pip
pip install torch==2.7.1 torchvision==0.22.1 --extra-index-url https://download.pytorch.org/whl/cu128
pip install -e .After preparing LIBERO data and the backbone, precompute text embeddings and launch the example MoT run. Adjust the GPU process count for your machine.
python scripts/precompute_text_embeds.py task=libero_easywam_mot_wan22
NPROC_PER_NODE=8 bash scripts/train_zero1.sh task=libero_easywam_mot_wan22Set up the simulator and data with its guide, then replace the checkpoint placeholder with your own file.
python experiments/libero/run_libero_manager.py \
  task=libero_easywam_mot_wan22 \
  ckpt=<path/to/checkpoint.pt>
03 / results
Task success rates (%), higher is better. Results may vary with checkpoints, seeds and evaluation settings.
EasyWAM-Hidden average success
EasyWAM-MoT average success
EasyWAM-Unified average success
| Model | Spatial | Object | Goal | LIBERO-10 | Avg. |
|---|---|---|---|---|---|
| EasyWAM-Unified | 98.4 | 98.8 | 99.2 | 98.0 | 98.6 |
| EasyWAM-MoT | 97.0 | 99.2 | 96.6 | 94.0 | 96.7 |
| EasyWAM-Hidden | 99.2 | 100.0 | 97.8 | 98.2 | 98.8 |
| Model | Spatial | Object | Goal | LIBERO-10 | Avg. |
|---|---|---|---|---|---|
| EasyWAM-Unified | 91.2 | 98.8 | 91.8 | 66.2 | 87.0 |
| EasyWAM-MoT | 96.8 | 99.6 | 97.4 | 90.0 | 95.9 |
| EasyWAM-Hidden | 98.0 | 99.8 | 89.4 | 86.6 | 93.5 |
| Model | Spatial | Object | Goal | LIBERO-10 | Avg. |
|---|---|---|---|---|---|
| EasyWAM-Unified | 97.8 | 99.4 | 97.0 | 93.0 | 96.8 |
| EasyWAM-MoT | 98.0 | 98.4 | 98.4 | 95.6 | 97.6 |
| EasyWAM-Hidden | 97.2 | 98.8 | 96.0 | 95.0 | 96.8 |
| Model | Orig | Background | Camera | Language | Layout | Light | Noise | Robot | Avg. |
|---|---|---|---|---|---|---|---|---|---|
| EasyWAM-Unified | 98.6 | 72.3 | 54.8 | 93.7 | 83.4 | 97.0 | 72.0 | 83.4 | 79.0 |
| EasyWAM-MoT | 96.7 | 64.5 | 45.5 | 71.4 | 80.1 | 94.7 | 78.5 | 71.5 | 71.7 |
| EasyWAM-Hidden | 98.8 | 59.3 | 57.0 | 93.2 | 84.3 | 95.0 | 70.8 | 83.7 | 77.6 |
| Model | Orig | Background | Camera | Language | Layout | Light | Noise | Robot | Avg. |
|---|---|---|---|---|---|---|---|---|---|
| EasyWAM-Unified | 96.8 | 72.7 | 63.7 | 90.1 | 82.6 | 89.2 | 72.1 | 79.2 | 78.2 |
| EasyWAM-MoT | 97.6 | 60.7 | 75.1 | 92.3 | 82.6 | 92.6 | 81.3 | 58.5 | 77.7 |
| EasyWAM-Hidden | 96.8 | 59.5 | 65.9 | 92.6 | 85.0 | 89.1 | 68.3 | 82.5 | 77.8 |
LIBERO-Plus uses LIBERO checkpoints and tests changes to background, camera, language, layout, lighting, noise and robot appearance.
04 / efficiency
EasyWAM provides efficiency controls across attention, memory, data loading and batched evaluation.
Choose the fastest compatible FlashAttention 4, 3 or 2 backend, with PyTorch SDPA as a fallback. BF16 training reduces tensor bandwidth and memory use.
LoRA, DeepSpeed ZeRO, gradient checkpointing and VAE micro-batching help fit larger workloads, with configurable speed and memory tradeoffs.
Sparse video decoding, indexed text caches, precomputed text embeddings and persistent DataLoader workers reduce repeated loading and processing.
Dynamic inference batching, multiple model workers per GPU, prompt caching and resumable evaluation improve GPU use and avoid repeated work.
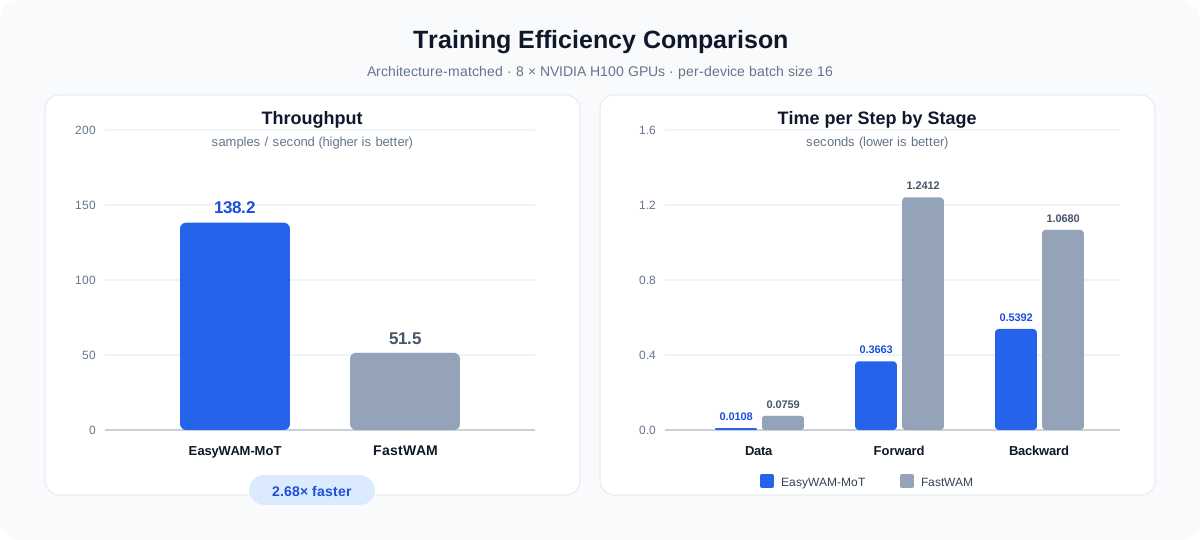
FastWAM: 51.5 samples/s
Versus the original FastWAM codebase
About 14 hours with original FastWAM
These results use the Wan2.2-TI2V-5B backbone on 8 × NVIDIA H100 GPUs with per-device batch size 16. EasyWAM-MoT and FastWAM share the same model architecture. Actual training time varies with CPU, GPU and data configuration.
| Framework | Throughput (samples/s) ↑ | Data (s) ↓ | Forward (s) ↓ | Backward (s) ↓ |
|---|---|---|---|---|
| EasyWAM-MoT | 138.2 | 0.0108 | 0.3663 | 0.5392 |
| FastWAM | 51.5 | 0.0759 | 1.2412 | 1.0680 |
05 / model zoo
These architectures and backbones are supported by the framework. Check the Hugging Face collection for released checkpoints.
Jointly predicts future video and actions in a single Video DiT.
Video DiT and Action DiT interact through mixed self-attention for action-only prediction.
Jointly denoises video and action tokens through mixed self-attention.
Uses teacher-forced conditional video for action prediction.
Conditions a separate Action DiT on intermediate Video DiT features.
Wan2.2-TI2V-5B · Cosmos-Predict2.5-2B · FLUX.2 Klein-4B
06 / community
Find guides, models and updates. Bring questions and ideas to the GitHub community.
Guides for backbones, data, training configuration and benchmarks.
Read the docs ↗ 02 / CODEBrowse code, configurations, updates and contribution guidance.
View repository ↗ 03 / MODELSFind published EasyWAM checkpoints and datasets.
Browse collection ↗ 04 / FEEDBACKReport issues, propose features or join the project discussion.
Open issues ↗Scan to join the WeChat discussion group, or email the project team.
Email the team ↗